Blog
We periodically release blogs covering topics such as hiring opportunities, introductions to our research results, announcements welcoming new lab members, and yearly summaries of our achievements, and so on.
2026
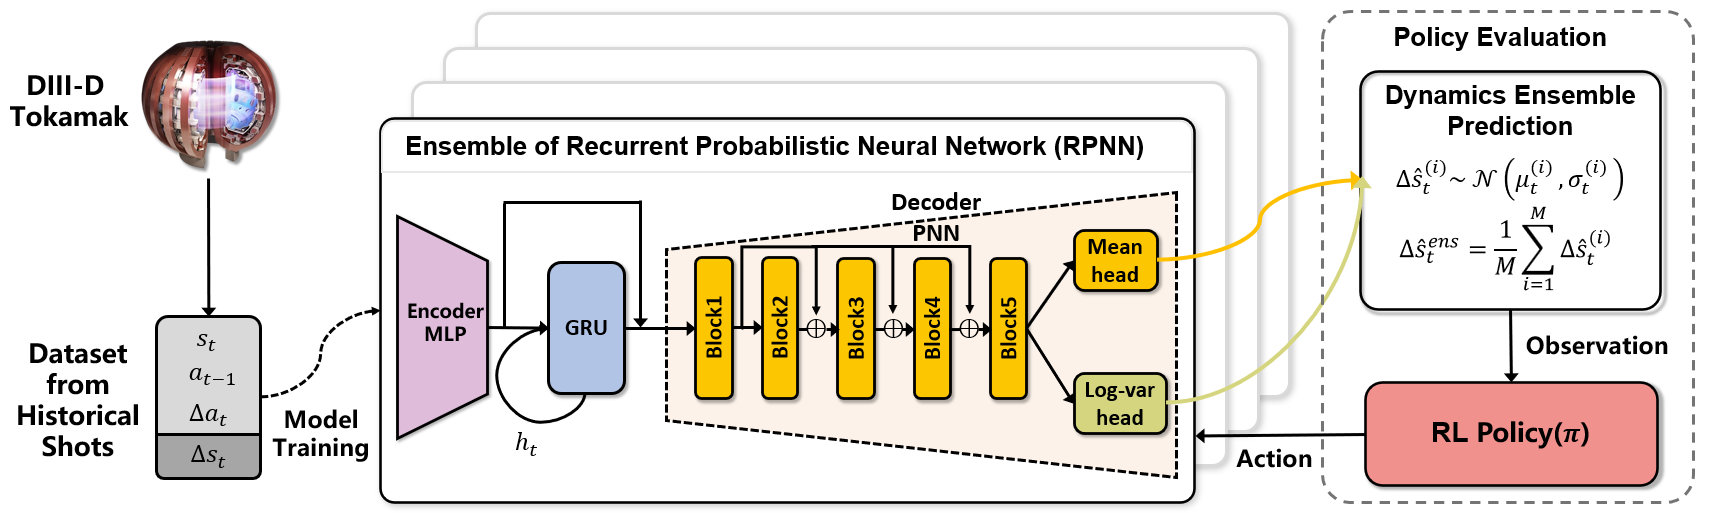
RL4F is an open-source benchmark for learning plasma controllers from offline data. Built around a dynamics ensemble trained on historical DIII-D tokamak discharges, it provides datasets, closed-loop evaluation environments, and baselines for rotation, density, electron temperature, and pressure profile tracking.
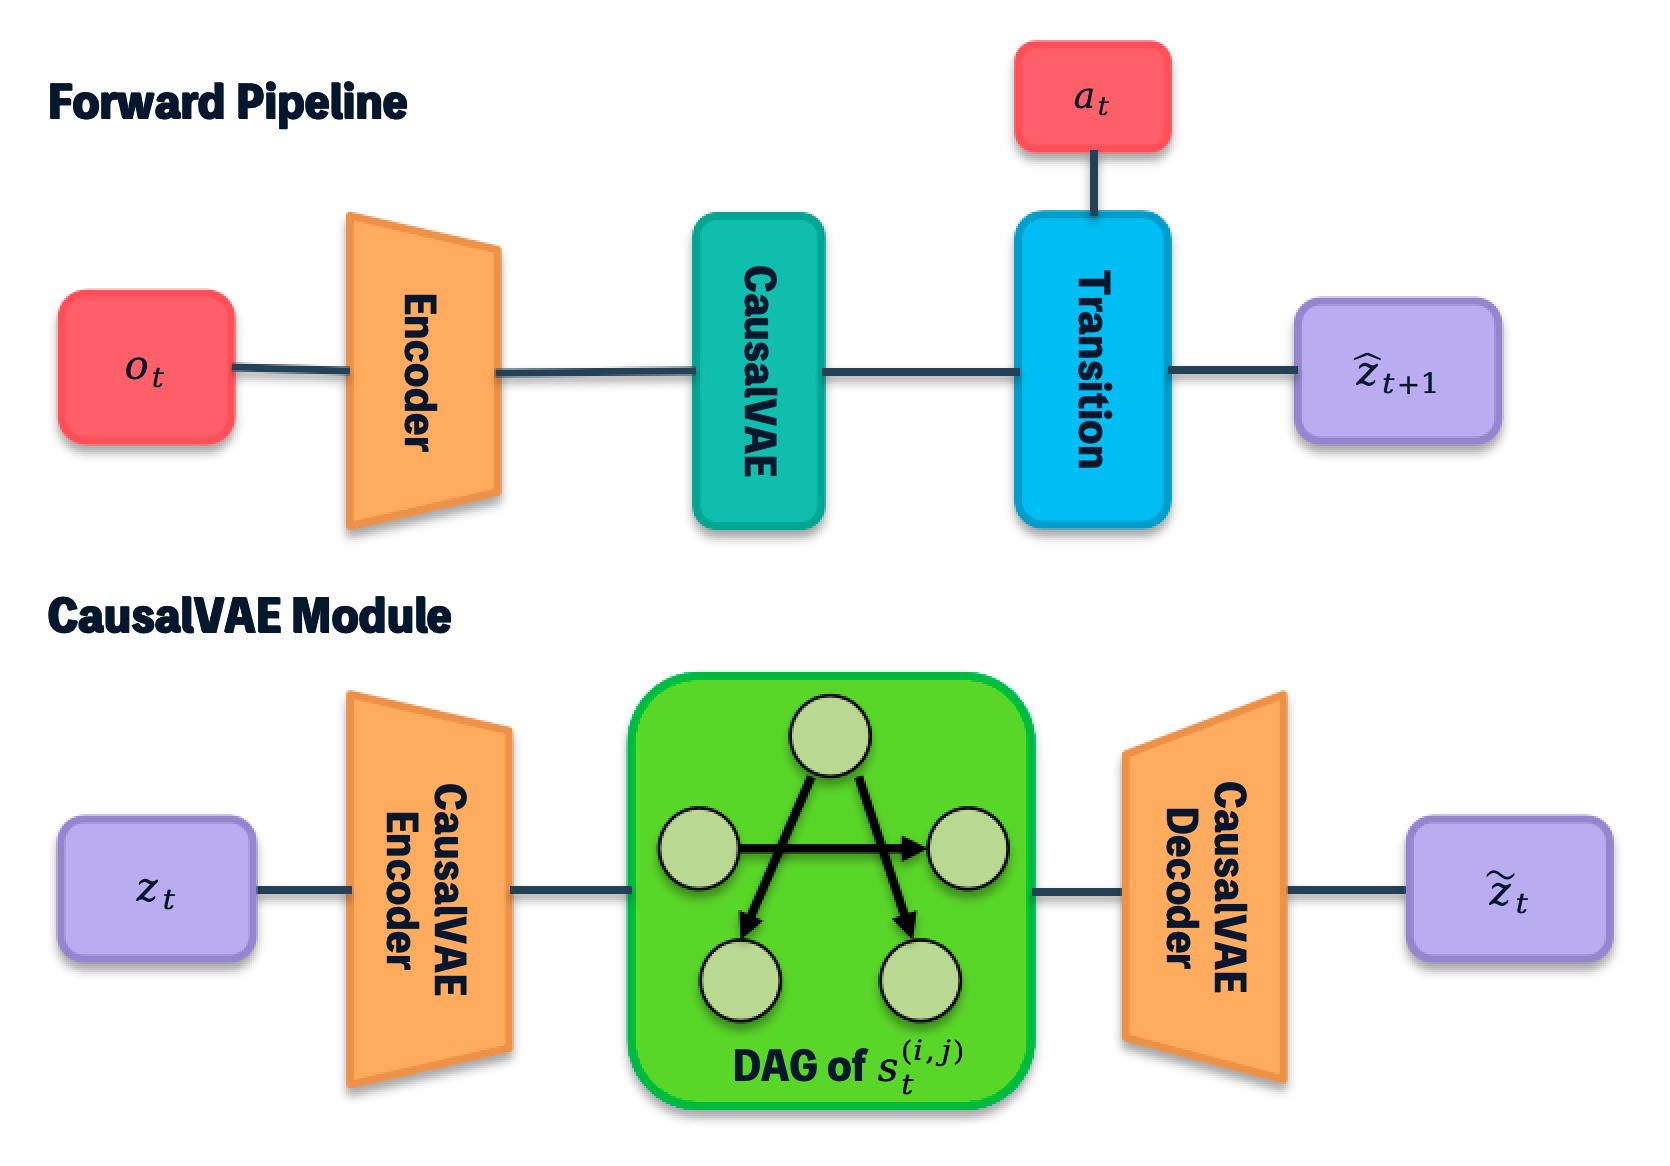
Predicting Is Not Yet Understanding
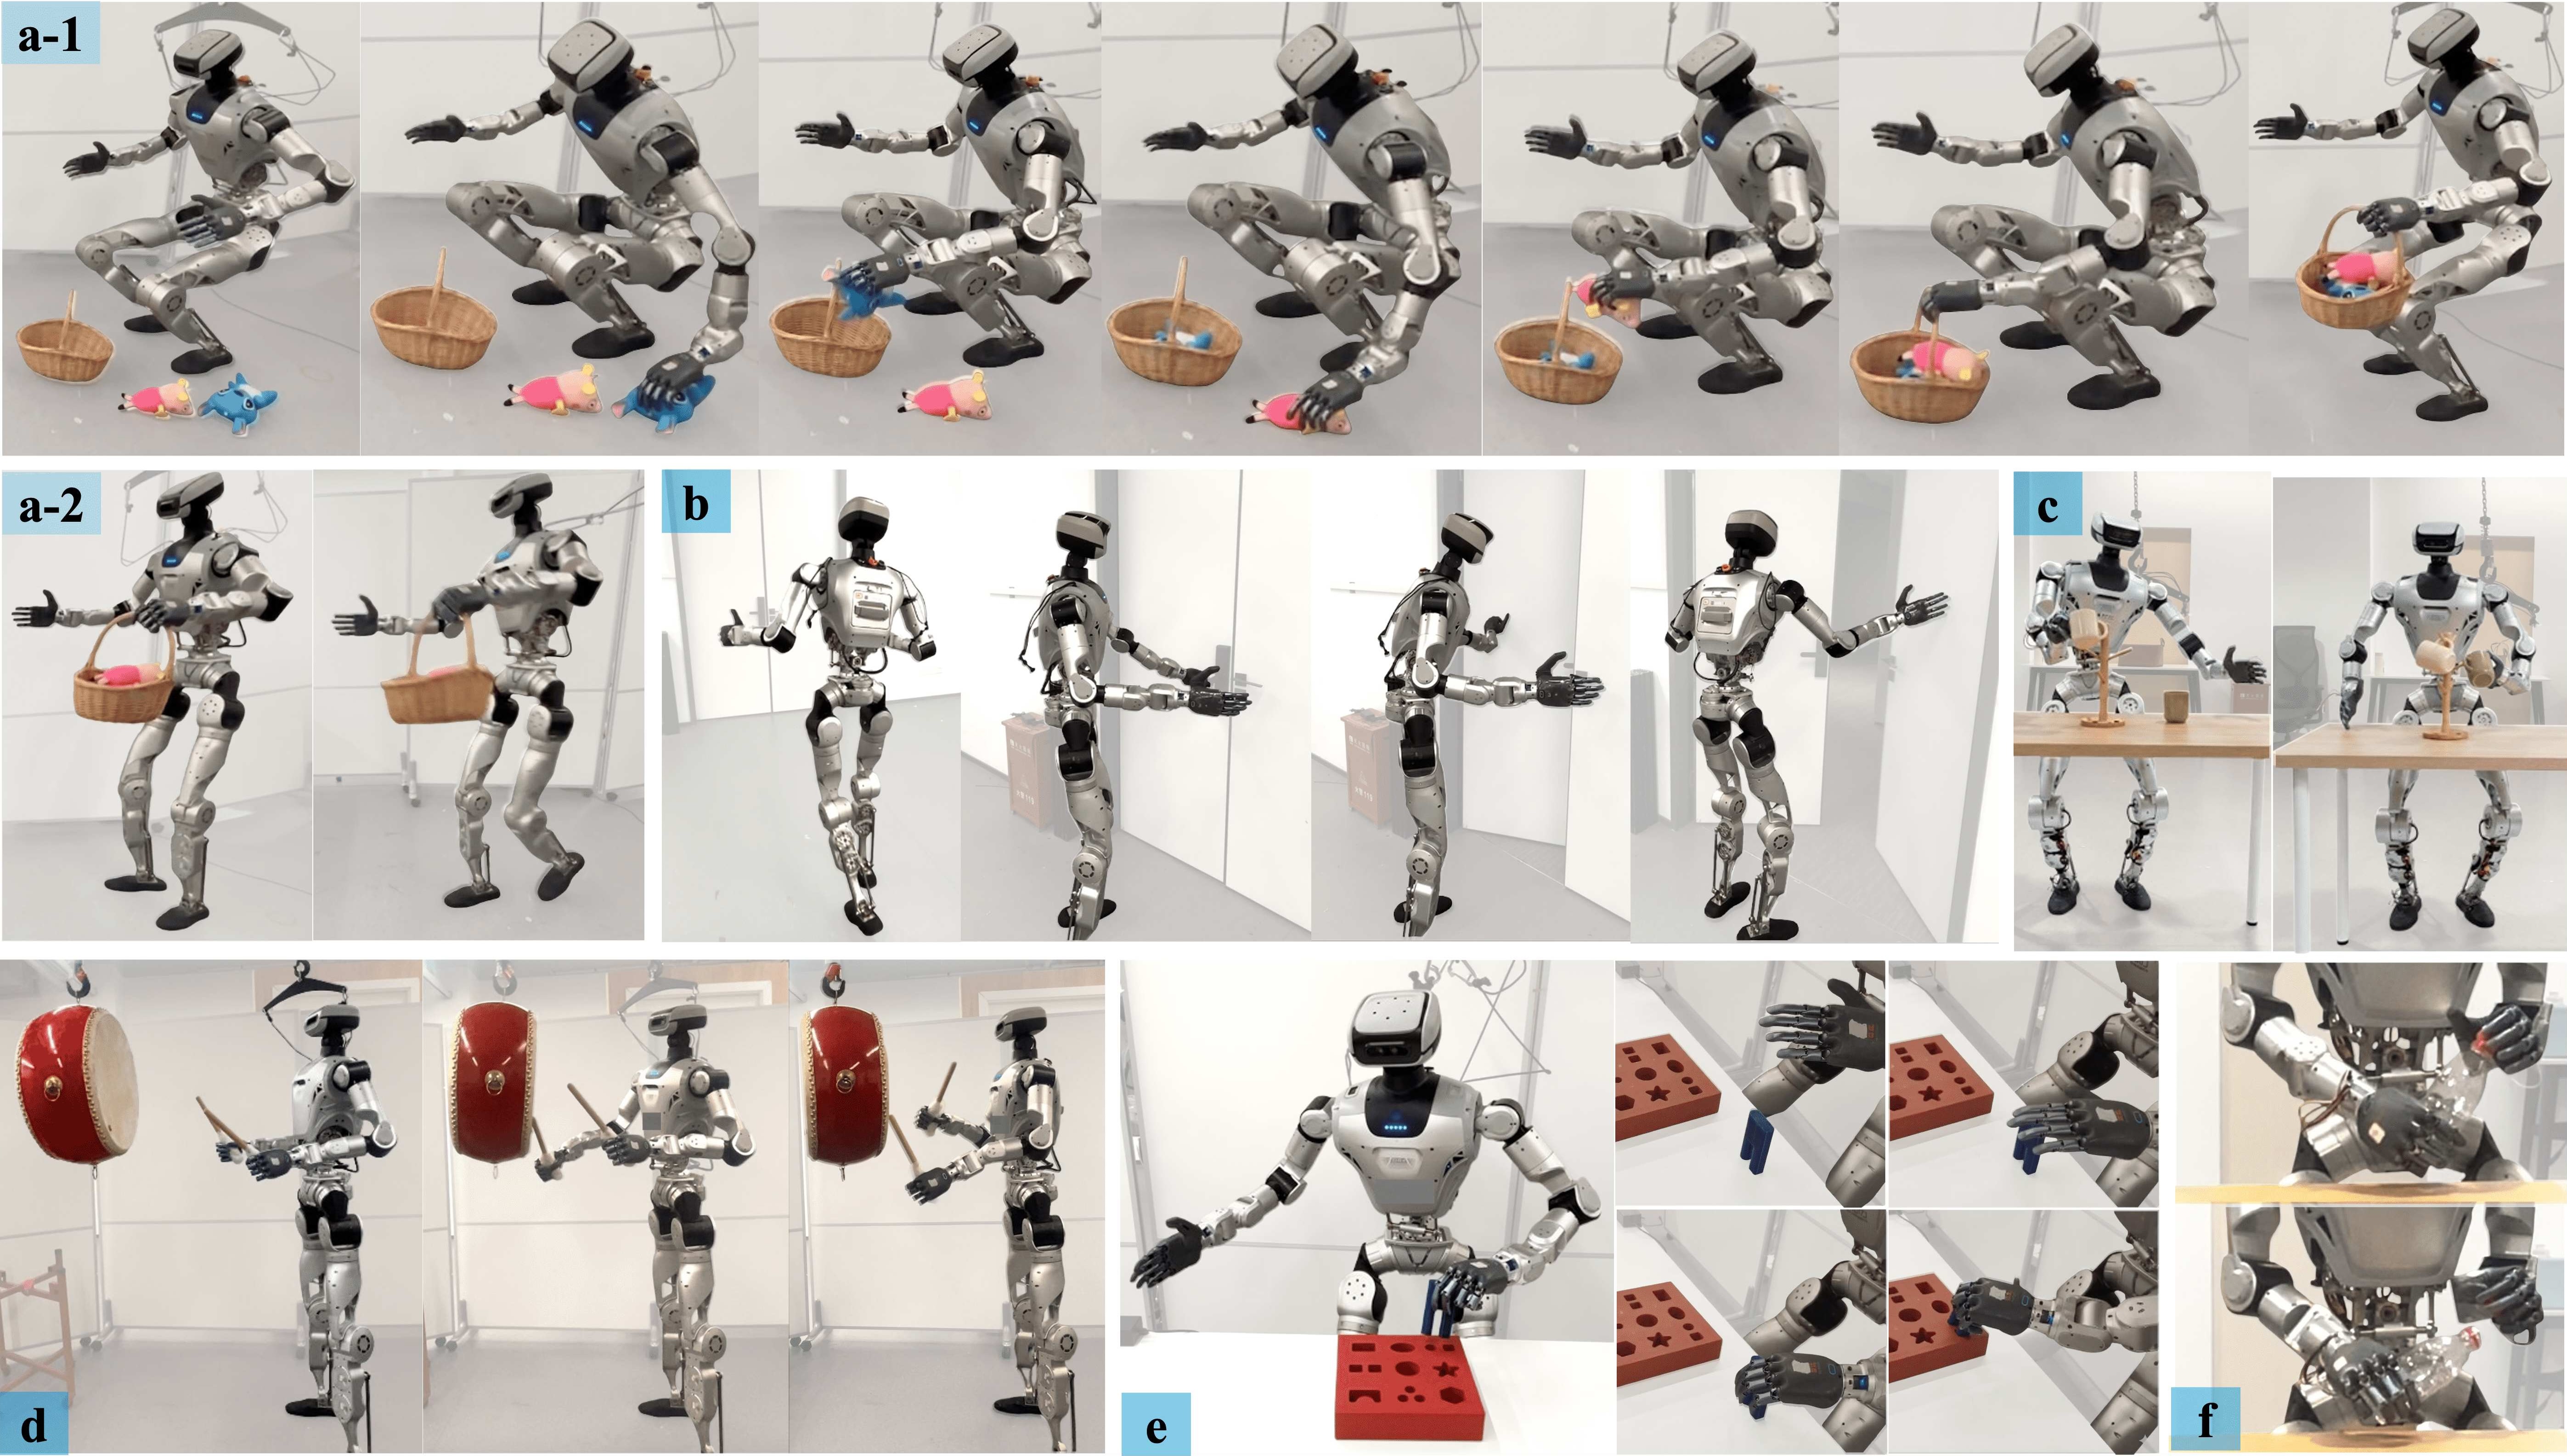
One Policy, Two Kinds of Motion Data
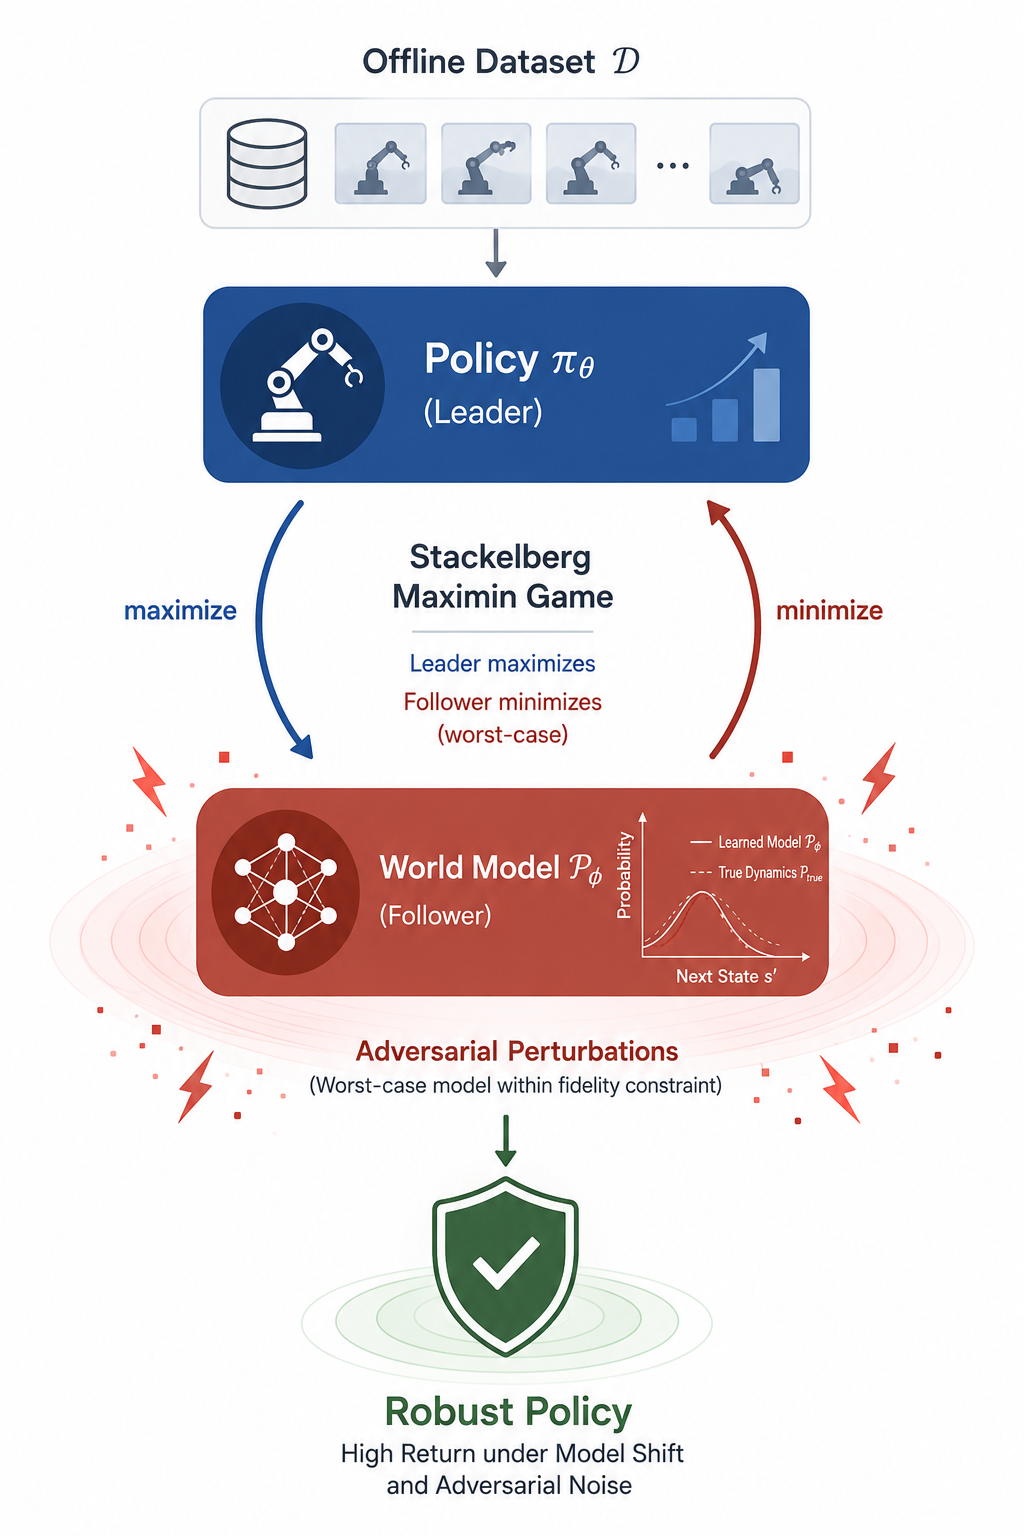
Our paper, “Policy-Driven World Model Adaptation for Robust Offline Model-based Reinforcement Learning”, was presented as a poster at ICML 2026 in Seoul, South Korea. This is joint work between the Agentic Intelligence Lab at the University of Hong Kong, Tsinghua University, and the Robotics Institute at Carnegie Mellon University.
Our paper, “On the Convergence of Self-Improving Online LLM Alignment,” appeared at the 42nd Conference on Uncertainty in Artificial Intelligence (UAI 2026). It addresses a basic theoretical gap behind self-improving alignment.
2025
Source Code
About the PI